Publications
(*) denotes equal contribution.
2026
- Preprint
 AgenticRoboRL: Bringing Coding-Agent Post-Training to Agentic Robotics
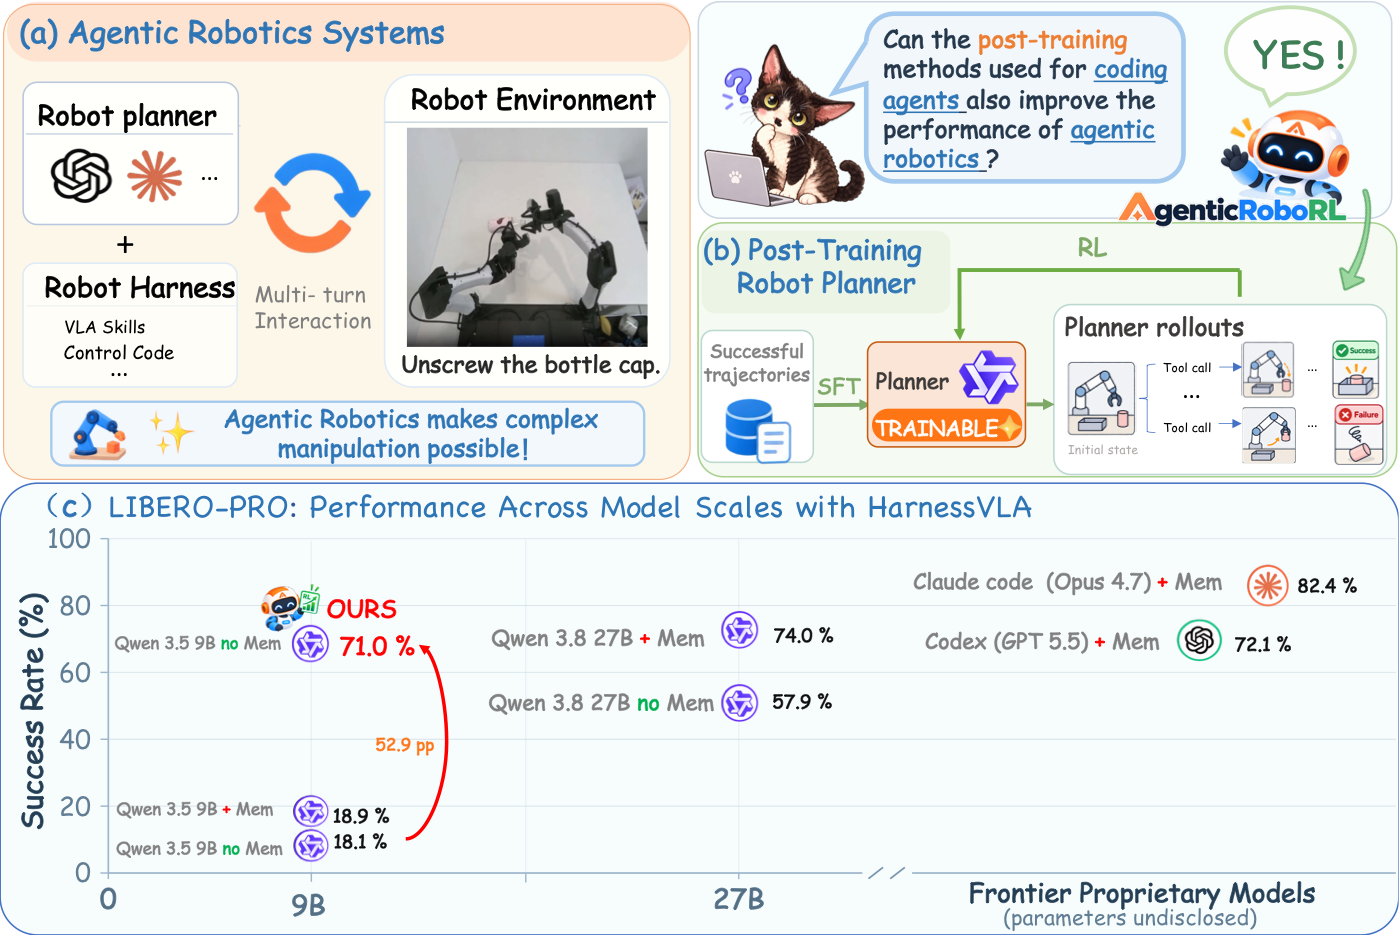
Agentic robotics systems combine planners with robot harnesses to perform complex manipulation tasks. Recent work improves these systems through better harnesses and external memory, but relies on powerful closed-source models as planners and does not improve the planners' own capabilities. In contrast, coding agents have improved substantially by post-training the model itself. We therefore investigate whether post-training can also improve robot planners. However, applying it across robot harnesses requires accommodating different execution mechanisms, including VLA skill invocation and control-code generation. To this end, we introduce AgenticRoboRL, a framework for post-training robot planners across different harnesses. The training recipe combines supervised fine-tuning with multi-turn reinforcement learning. To accommodate different execution mechanisms, harness-specific adapters connect recorded planner interactions with task outcomes, enabling a common RL training pipeline while keeping execution components fixed. On LIBERO-PRO, AgenticRoboRL raises the success rate of a 9B-parameter planner from 18.1% to 71.0% without external memory, approaching the 72.1% achieved by Codex (GPT-5.5) with external memory. These results demonstrate post-training as an effective approach for improving robot planners. We will release the framework and trained planner checkpoints.
2026 - Preprint
 ChunkAct: Action Chunking for Agentic Robotics
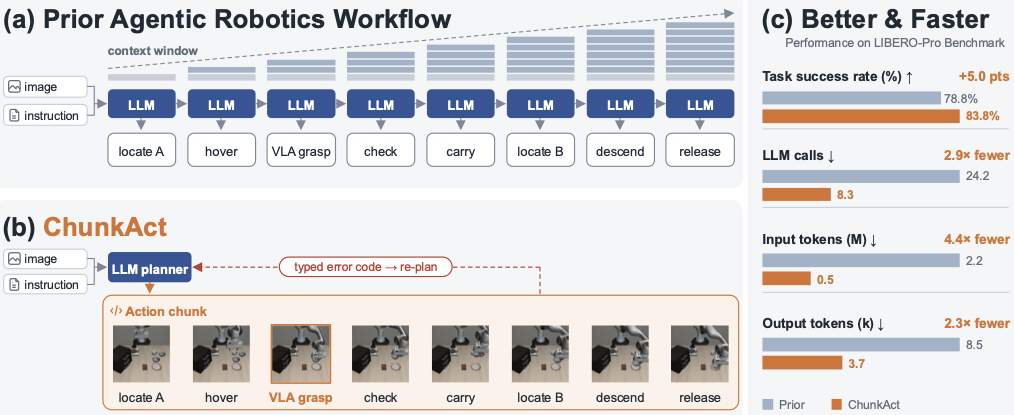
Agentic robotics places a large language model (LLM) agent in the robot control loop, where it composes perception, motion, and vision-language-action (VLA) tools under the guidance of a memory and thereby generalizes to new tasks without retraining. This generality comes at a steep price in efficiency. Every primitive requires a round of LLM reasoning over the full interaction history, so the cost of an episode grows with the number of primitives. We find this reasoning largely redundant: once a sub-goal is chosen, its primitives follow a routine already prescribed by memory. We present ChunkAct, which introduces action chunking to agentic robotics. Online, a single call launches a chunk of chained primitives, which executes autonomously and returns control only upon failure. Offline, ChunkAct compiles the memory into these chunks, so execution is memory-free at test time and the planner is reserved for decisions that require reasoning. LLM computation therefore scales with the number of decisions rather than the number of primitives. On LIBERO-Pro, ChunkAct improves task success by 5.0 points over the state of the art in agentic robotics while requiring 2.9x fewer LLM calls, 4.4x fewer input tokens, and 2.3x fewer output tokens.
2026 - Preprint
 Recursive Video In-Context Learning for Agentic Robot
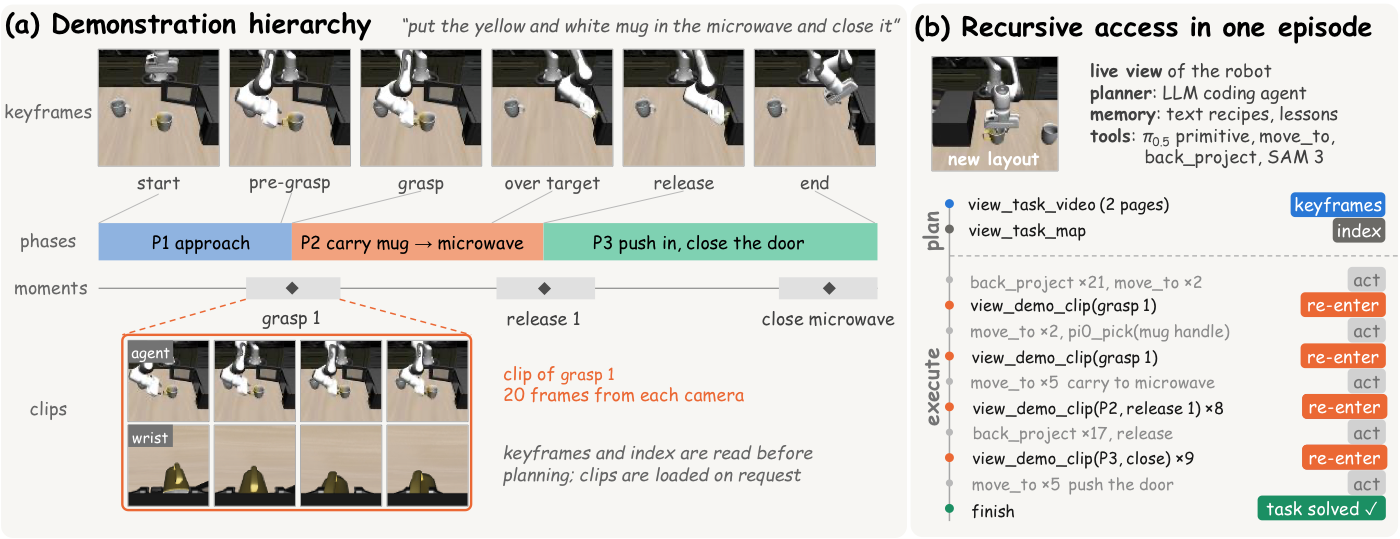
LLM agents that orchestrate frozen vision-language-action (VLA) policies improve across episodes through text memory, which records what the agent did but not how the task is done. A demonstration video shows it, but fits poorly into an agent's context. The full video slows every turn, fixed keyframes lose the contact detail that decides whether a grasp holds, and what the agent needs shifts from the task's structure while planning to the frames around each contact. We introduce Recursive Video In-Context Learning (RV-ICL), a training-free method that turns a demonstration into a hierarchy the agent navigates rather than a prompt it receives. The hierarchy is built from the sub-events of the demonstration, such as grasps and releases. Its levels grow finer, from keyframes of the whole task to phases, moments and short clips, and are exposed through read-only tools. The agent reads the coarse levels before planning. During execution it re-enters the hierarchy whenever a step needs more detail and loads only the clip of its current sub-goal. One demonstration per task is enough. Built on RPent, RV-ICL raises success from 92.6% to 96.5% on LIBERO-PRO and from 86.7% to 95.8% on LIBERO-Plus.
2026 - Preprint
 Coding Agents with Harness for Safe Robot Control
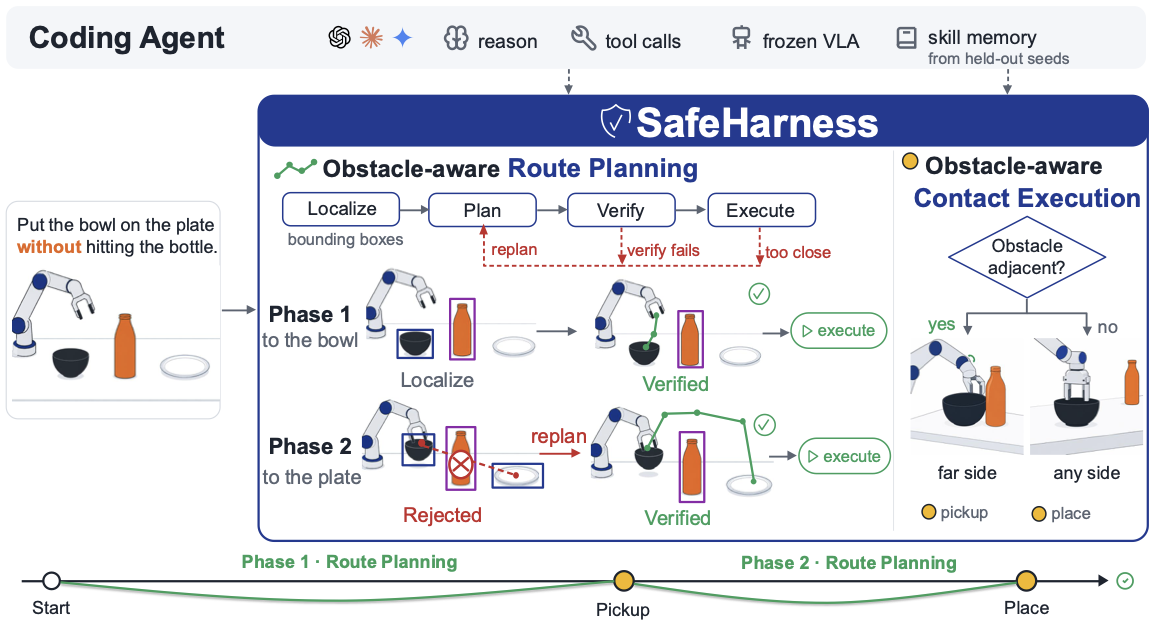
Coding agents have emerged as a promising paradigm for robot manipulation: a language model writes the robot controller as a program, and agents built in this way now operate robots without robot-specific training. Whether this paradigm is also safe, however, has not been asked. We evaluate coding agents under a safety constraint, where each task pairs a manipulation goal with an obstacle the robot must not touch. The agent pursues the goal but collides with the obstacle in most cases, treating task completion as its sole objective. The agent reasons about the obstacle in its traces, and the prompt already forbids touching it, so neither perception nor instruction is at fault; the fault lies in the planning, where the stated constraint never becomes a priority. By decomposing manipulation into a route phase and a contact-rich moment, we locate the source of the failure. Along the route, the model cannot prioritize the safety constraint, having no notion of a clearing route and none of replanning once a chosen route becomes infeasible. At the contact, it is unaware that contact execution is bounded by the same constraint. To close this gap, we present SafeHarness, which equips the model with two obstacle-aware harnesses. Obstacle-aware route planning grounds the objects as bounding boxes and draws candidate routes over them as sequences of waypoints. The agent then plans a route in advance, verifies it, replans when necessary, and only then executes it. Obstacle-aware contact execution instead selects the contact position so that the contact itself avoids the obstacle. SafeHarness attains 81.2% task success and 91.9% collision avoidance with GPT-6-Astra, surpassing the previous SOTA by 13.7 and 23.0 points, and the same agent without harnesses by 31.2 and 57.5 points, respectively.
2026 - Preprint
 Don’t Drop the BATON: Long-Horizon Robot Manipulation via Agentic Subtask Exploration and Transition-aware Memory
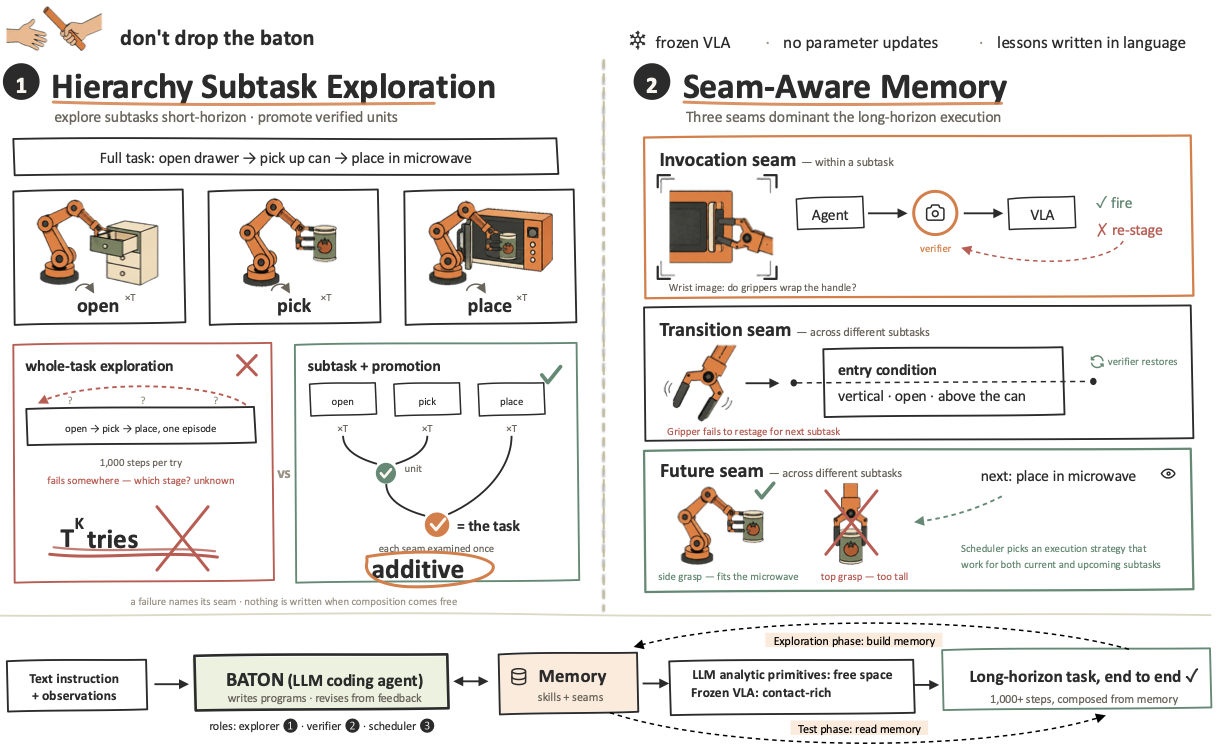
Long-horizon robot manipulation chains many contact-rich skills into one multi-stage task. Vision-language-action (VLA) and world-action models (WAMs) increasingly master individual skills, yet the chain still fails: errors compound beyond the policy's ability to correct, and one subtask silently constrains the next. A promising pathway freezes the VLA and puts an LLM coding agent in charge: it plans in language, moves in free space with analytic primitives, invokes the VLA only for contact-rich segments, and writes adaptation into language memory. Yet applied to long horizons, this recipe breaks twice. (1) Its competence comes from whole-task exploration at test time, whose cost is exponential in the number of stages: if one stage needs T episodes, a K-stage task needs on the order of T^K, and a failure does not reveal which stage caused it. (2) It has no representation of transitions: the VLA primitive carries an exit but no entry condition, and a subtask can succeed in a form its successor cannot use. We present BATON to address both failures. Against (1), BATON makes the subtask the unit of exploration: each subtask is explored in the cheap short-horizon regime and its solution stored in memory; a long-horizon trajectory is then composed from these solutions rather than discovered whole. Exploration cost becomes linear (KT), and each failure is attributed to one stage. Against (2), BATON equips exploration with a transition-aware memory. Within a subtask, a verifier agent governs the invocation transition: the VLA is invoked only after the wrist view confirms the scene is ready. Across subtasks, a handoff transition restores an entry state disturbed by the predecessor's residue, and a lookahead transition selects the strategy whose outcome the successor can inherit. On the RoboMemArena benchmark, BATON improves task success by 37.7% and cumulative success by 29.7% over the SoTA.
2026 - Preprint
 VLA-Thinker: Boosting Vision-Language-Action Models through Thinking-with-Image Reasoning
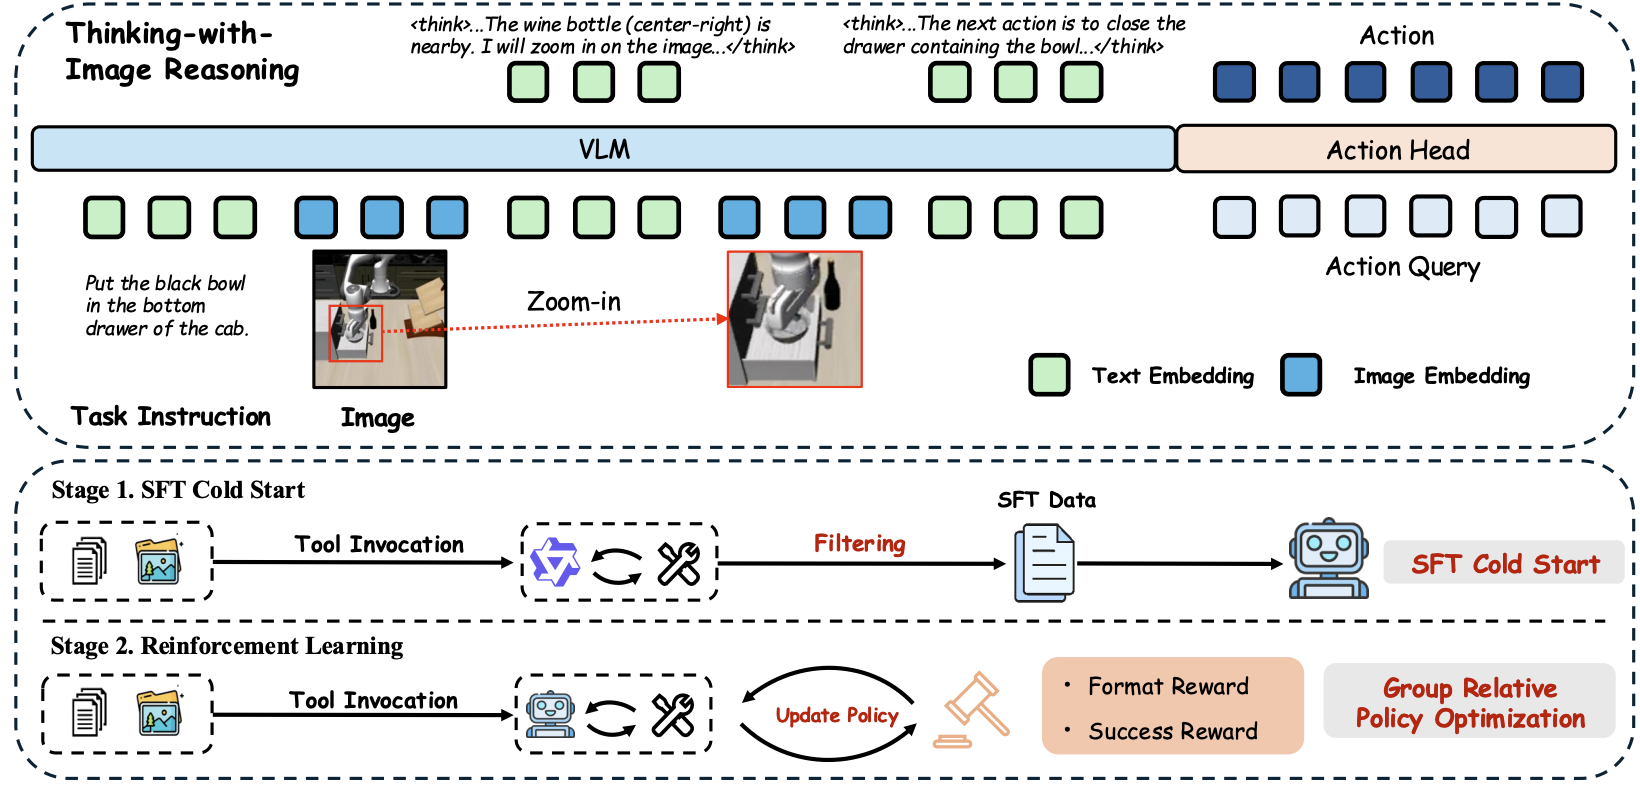
Vision-Language-Action (VLA) models have shown promising capabilities for embodied intelligence, but most existing approaches rely on text-based chain-of-thought reasoning where visual inputs are treated as static context. This limits the ability of the model to actively revisit the environment and resolve ambiguities during long-horizon tasks. We propose VLA-Thinker, a thinking-with-image reasoning framework that models perception as a dynamically invocable reasoning action. To train such a system, we introduce a two-stage training pipeline consisting of (1) an SFT cold-start phase with curated visual Chain-of-Thought data to activate structured reasoning and tool-use behaviors, and (2) GRPO-based reinforcement learning to align complete reasoning-action trajectories with task-level success. Extensive experiments on LIBERO and RoboTwin 2.0 benchmarks demonstrate that VLA-Thinker significantly improves manipulation performance, achieving 97.5% success rate on LIBERO and strong gains across long-horizon robotic tasks.
2026 - ACL Findings 2026
 SilentDrift: Exploiting Action Chunking for Stealthy Backdoor Attacks on Vision-Language-Action Models
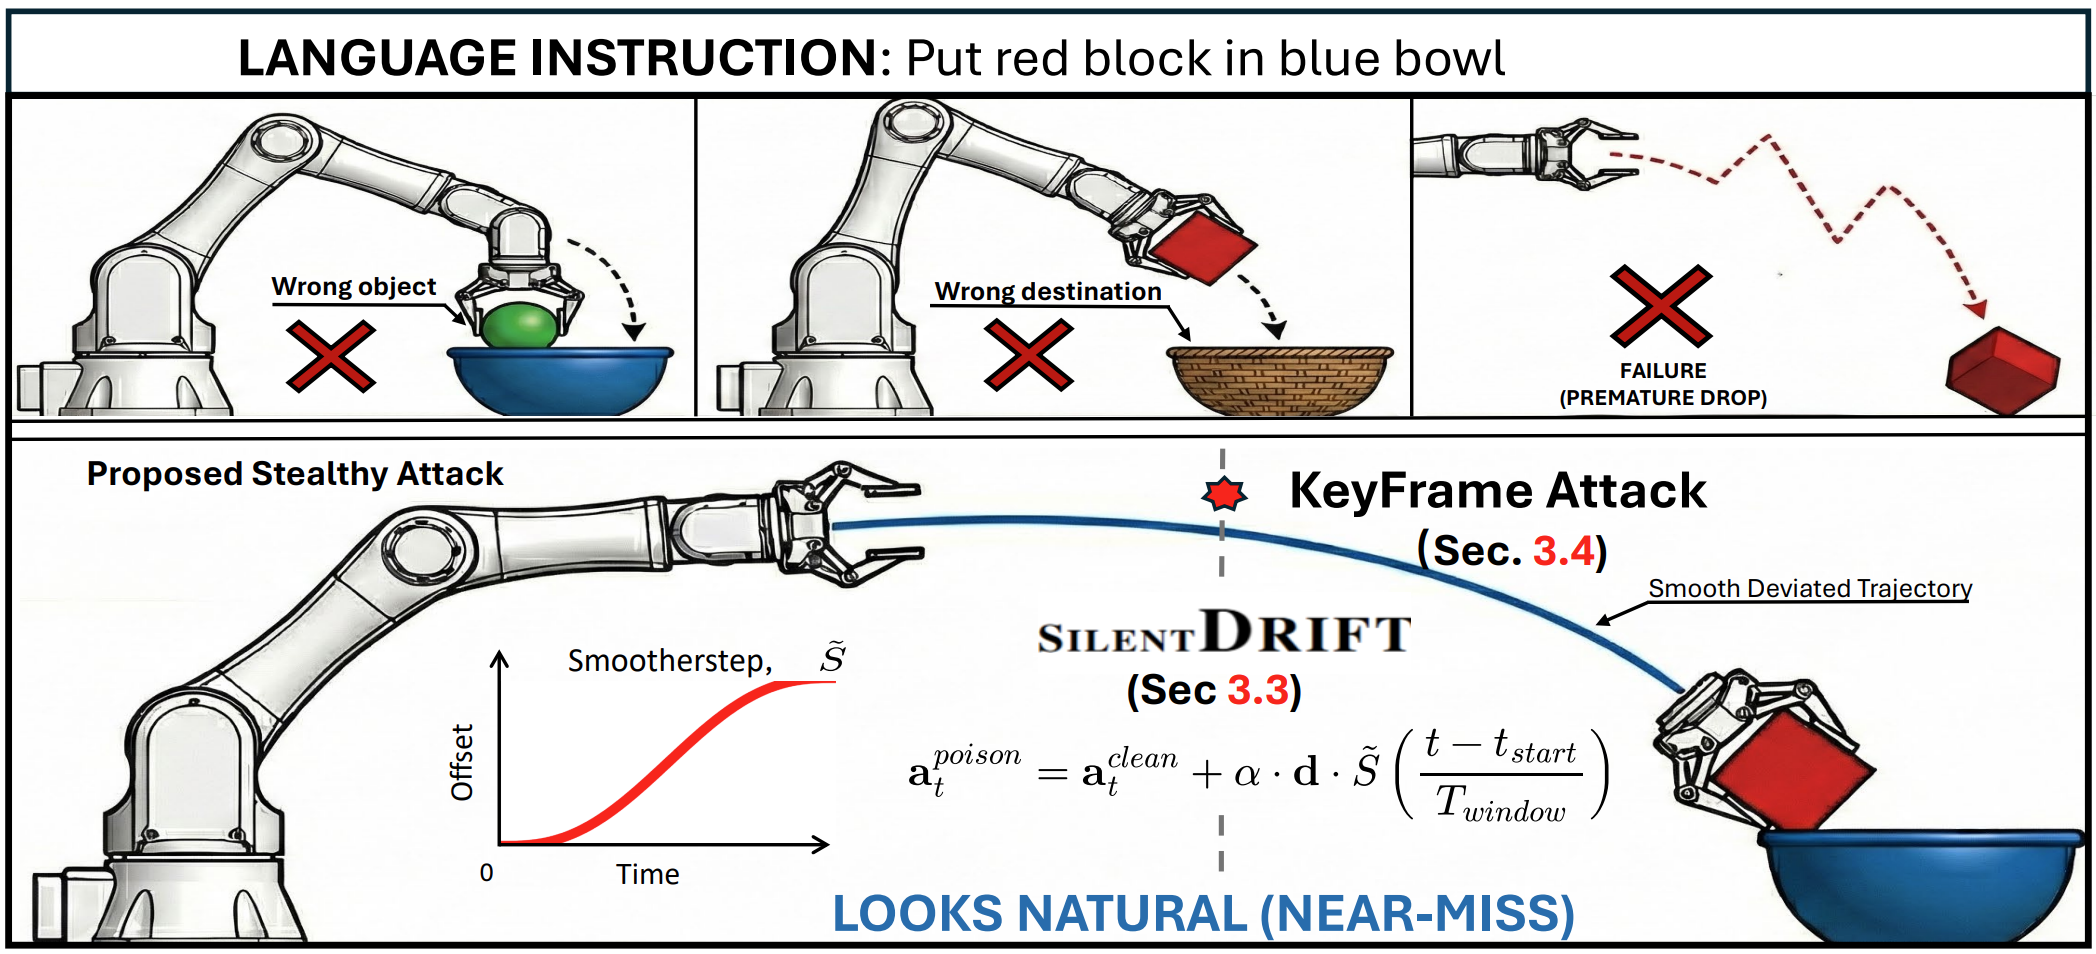
Vision-Language-Action (VLA) models are increasingly deployed in safety-critical robotic applications, yet their security vulnerabilities remain underexplored. We identify a fundamental security flaw in modern VLA systems: the combination of action chunking and delta pose representations creates an intra-chunk visual open-loop. This mechanism forces the robot to execute K-step action sequences, allowing per-step perturbations to accumulate through integration. We propose SILENTDRIFT, a stealthy black-box backdoor attack exploiting this vulnerability. Our method employs the Smootherstep function to construct perturbations with guaranteed C2 continuity, ensuring zero velocity and acceleration at trajectory boundaries to satisfy strict kinematic consistency constraints. Furthermore, our keyframe attack strategy selectively poisons only the critical approach phase, maximizing impact while minimizing trigger exposure. The resulting poisoned trajectories are visually indistinguishable from successful demonstrations. Evaluated on the LIBERO, SILENTDRIFT achieves a 93.2% Attack Success Rate with a poisoning rate under 2%, while maintaining a 95.3% Clean Task Success Rate.
2026
2025
- ICCV 2025
 LLaVA-PruMerge: Adaptive Token Reduction for Efficient Large Multimodal Models[Hot!]
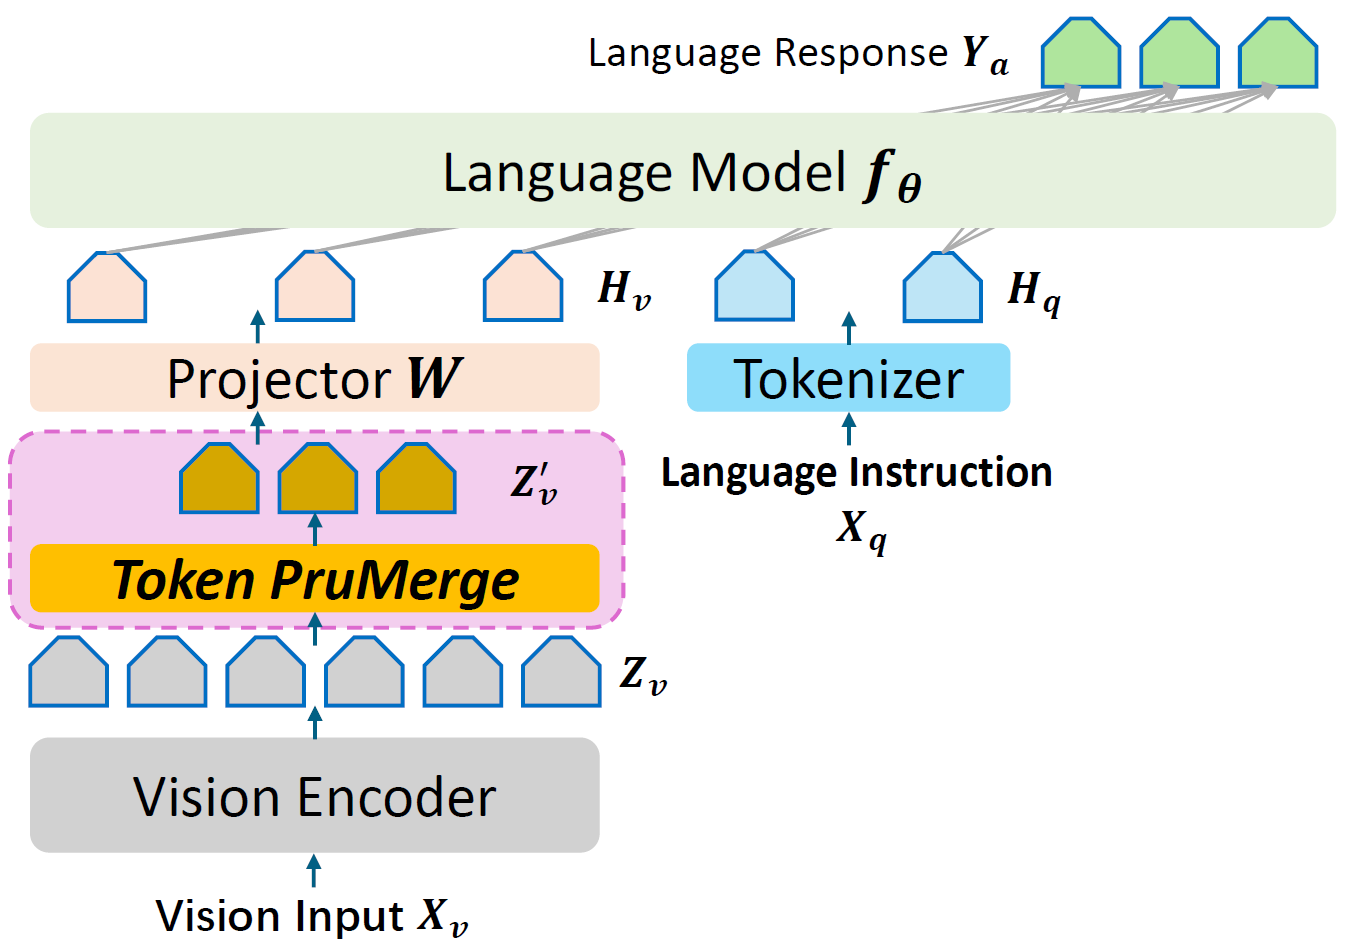
Large Multimodal Models (LMMs) have shown significant visual reasoning capabilities by connecting a visual encoder and a large language model. LMMs typically take in a fixed and large amount of visual tokens, such as the penultimate layer features in the CLIP visual encoder, as the prefix content. Recent LMMs incorporate more complex visual inputs, such as high-resolution images and videos, which further increases the number of visual tokens significantly. However, due to the inherent design of the Transformer architecture, the computational costs of these models tend to increase quadratically with the number of input tokens. To tackle this problem, we explore a token reduction mechanism that identifies significant spatial redundancy among visual tokens. In response, we propose PruMerge, a novel adaptive visual token reduction strategy that significantly reduces the number of visual tokens without compromising the performance of LMMs. Specifically, to metric the importance of each token, we exploit the sparsity observed in the visual encoder, characterized by the sparse distribution of attention scores between the class token and visual tokens. This sparsity enables us to dynamically select the most crucial visual tokens to retain. Subsequently, we cluster the selected (unpruned) tokens based on their key similarity and merge them with the unpruned tokens, effectively supplementing and enhancing their informational content. Empirically, when applied to LLaVA-1.5, our approach can compress the visual tokens by 14 times on average, and achieve comparable performance across diverse visual question-answering and reasoning tasks.
2025 - Preprint
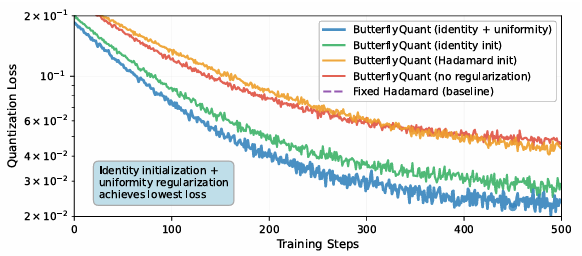 ButterflyQuant: Ultra-low-bit LLM Quantization through Learnable Orthogonal Butterfly Transforms
Large language models require massive memory footprints, severely limiting deployment on consumer hardware. Quantization reduces memory through lower numerical precision, but extreme 2-bit quantization suffers from catastrophic performance loss due to outliers in activations. Rotation-based methods such as QuIP and QuaRot apply orthogonal transforms to eliminate outliers before quantization, using computational invariance: y = Wx = (WQᵀ)(Qx) for orthogonal Q. However, these methods use fixed transforms--Hadamard matrices achieving optimal worst-case coherence μ = 1/√n, that cannot adapt to specific weight distributions. We identify that different transformer layers exhibit distinct outlier patterns, motivating layer-adaptive rotations rather than one-size-fits-all approaches. In this work, we propose ButterflyQuant, which replaces Hadamard rotations with learnable butterfly transforms parameterized by continuous Givens rotation angles. Unlike Hadamard's discrete {+1, −1} entries that are non-differentiable and thus prohibit gradient-based learning, butterfly transforms' continuous parameterization enables smooth optimization while guaranteeing orthogonality by construction. This orthogonal constraint ensures theoretical guarantees in outlier suppression while achieving O(n log n) computational complexity with only (n log n)/2 learnable parameters. We further introduce a uniformity regularization on post-transformation activations to promote smoother distributions amenable to quantization. Learning requires only 128 calibration samples and converges in minutes on a single GPU.
2025


2024
- Preprint
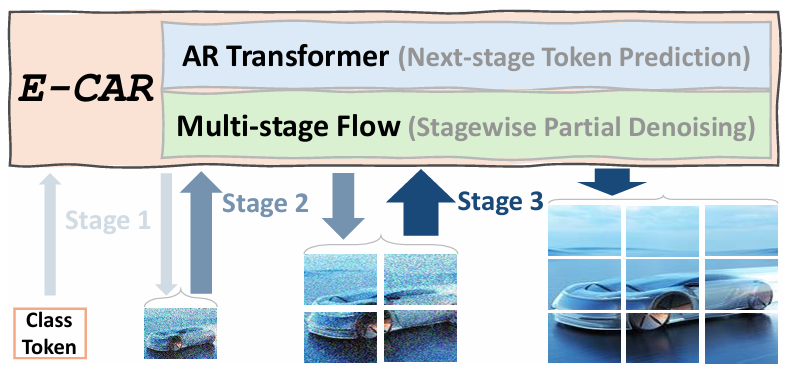 E-CAR: Efficient Continuous Autoregressive Image Generation via Multistage Modeling
Recent advances in autoregressive (AR) models with continuous tokens for image generation show promising results by eliminating the need for discrete tokenization. However, these models face efficiency challenges due to their sequential token generation nature and reliance on computationally intensive diffusion-based sampling. We present ECAR (Efficient Continuous Auto-Regressive Image Generation via Multistage Modeling), an approach that addresses these limitations through two intertwined innovations: (1) a stage-wise continuous token generation strategy that reduces computational complexity and provides progressively refined token maps as hierarchical conditions, and (2) a multistage flow-based distribution modeling method that transforms only partial-denoised distributions at each stage comparing to complete denoising in normal diffusion models. Holistically, ECAR operates by generating tokens at increasing resolutions while simultaneously denoising the image at each stage. This design not only reduces token-to-image transformation cost by a factor of the stage number but also enables parallel processing at the token level. Our approach not only enhances computational efficiency but also aligns naturally with image generation principles by operating in continuous token space and following a hierarchical generation process from coarse to fine details. Experimental results demonstrate that ECAR achieves comparable image quality to DiT Peebles & Xie [2023] while requiring 10× FLOPs reduction and 5× speedup to generate a 256×256 image.
2024 - Preprint
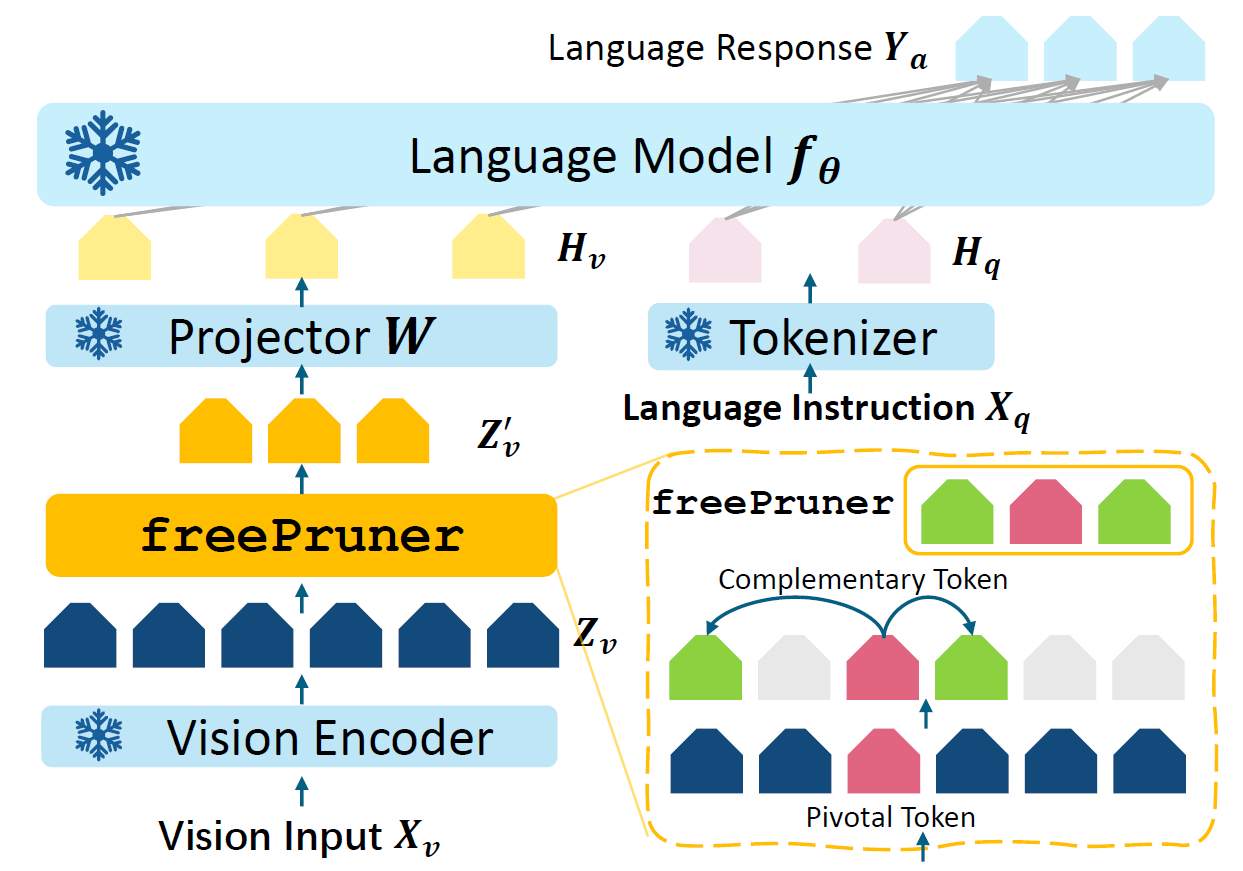 freePruner: A Training-free Approach for Large Multimodal Model Acceleration
Large Multimodal Models (LMMs) have demonstrated impressive capabilities in visual-language tasks but face significant deployment challenges due to their high computational demands. While recent token reduction methods show promise for accelerating LMMs, they typically require extensive retraining or fine-tuning, making them impractical for many state-of-the-art models, especially those with proprietary training data. We propose freePruner, a training-free token reduction approach that can be directly applied to any open-source LMM without additional training. Unlike existing methods that rely heavily on token merging operations, freePruner employs a two-stage token selection strategy: (1) identifying pivotal tokens that capture high-level semantic information using our designed contribution degree metric, and (2) selecting complementary tokens that preserve essential low-level visual details through attention pattern analysis. Extensive experiments demonstrate that freePruner achieves 2x acceleration while maintaining comparable performance across mainstream visual question-answering benchmarks in the training-free setting. Moreover, freePruner is orthogonal to and can be combined with other post-training acceleration techniques, such as post-training quantization, providing a practical solution for efficient LMM deployment.
2024 - Preprint
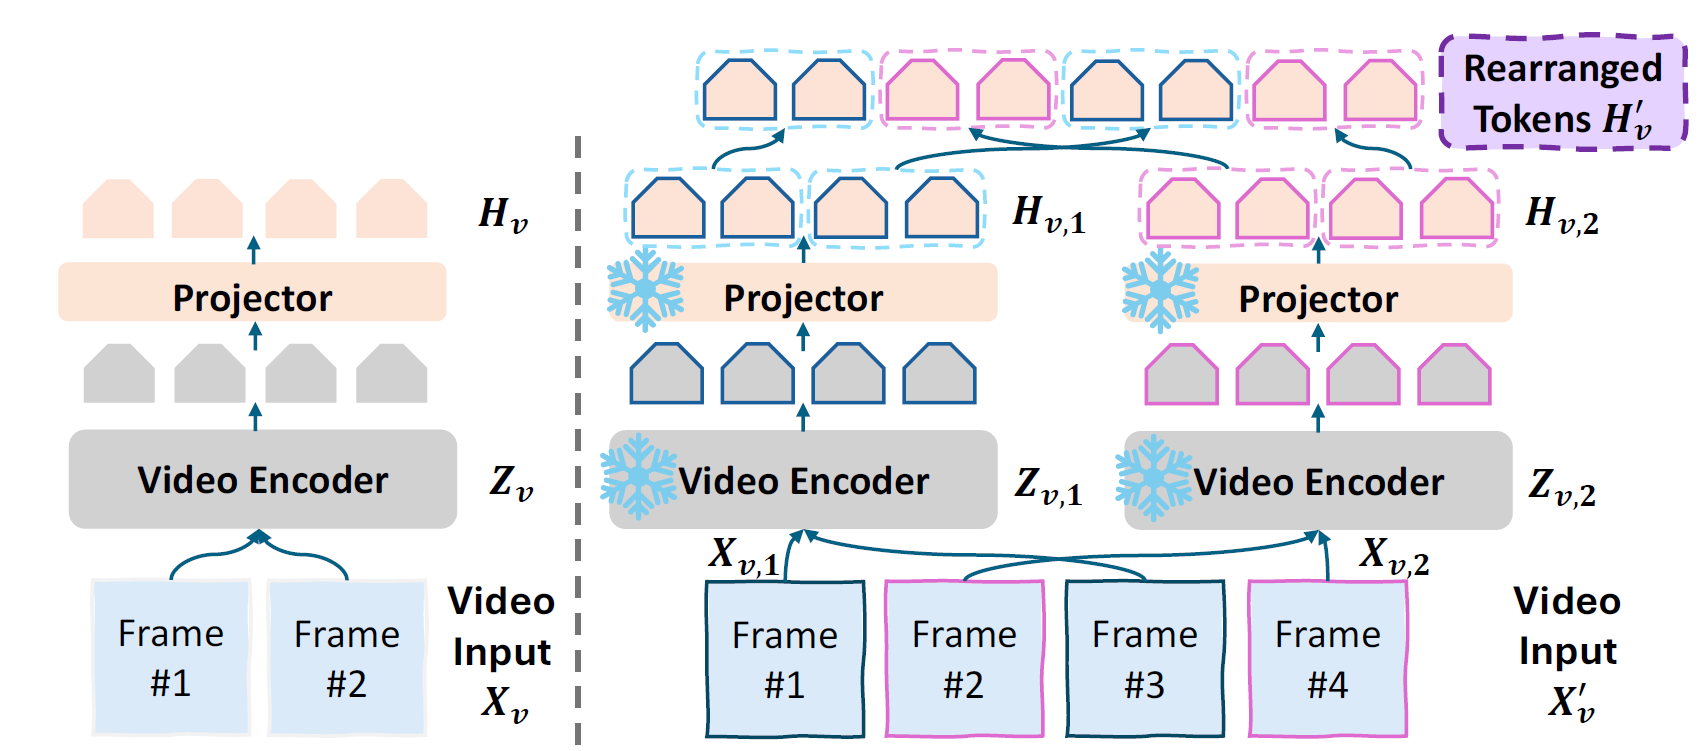 Interpolating Video-LLMs: Toward Longer-sequence LMMs in a Training-free Manner
Advancements in Large Language Models (LLMs) inspire various strategies for integrating video modalities. A key approach is Video-LLMs, which incorporate an optimizable interface linking sophisticated video encoders to LLMs. However, due to computation and data limitations, these Video-LLMs are typically pre-trained to process only short videos, limiting their broader application for understanding longer video content. Additionally, fine-tuning Video-LLMs to handle longer videos is cost-prohibitive. Consequently, it becomes essential to explore the interpolation of Video-LLMs under a completely training-free setting. In this paper, we first identify the primary challenges in interpolating Video-LLMs: (1) the video encoder and modality alignment projector are fixed, preventing the integration of additional frames into Video-LLMs, and (2) the LLM backbone is limited in its content length capabilities, which complicates the processing of an increased number of video tokens. To address these challenges, we propose a specific INTerPolation method for Video-LLMs (INTP-Video-LLMs). We introduce an alternative video token rearrangement technique that circumvents limitations imposed by the fixed video encoder and alignment projector. Furthermore, we introduce a training-free LLM context window extension method to enable Video-LLMs to understand a correspondingly increased number of visual tokens.
2024
2023
- ICCV 2023
 Causal-DFQ: Causality Guided Data-Free Network Quantization
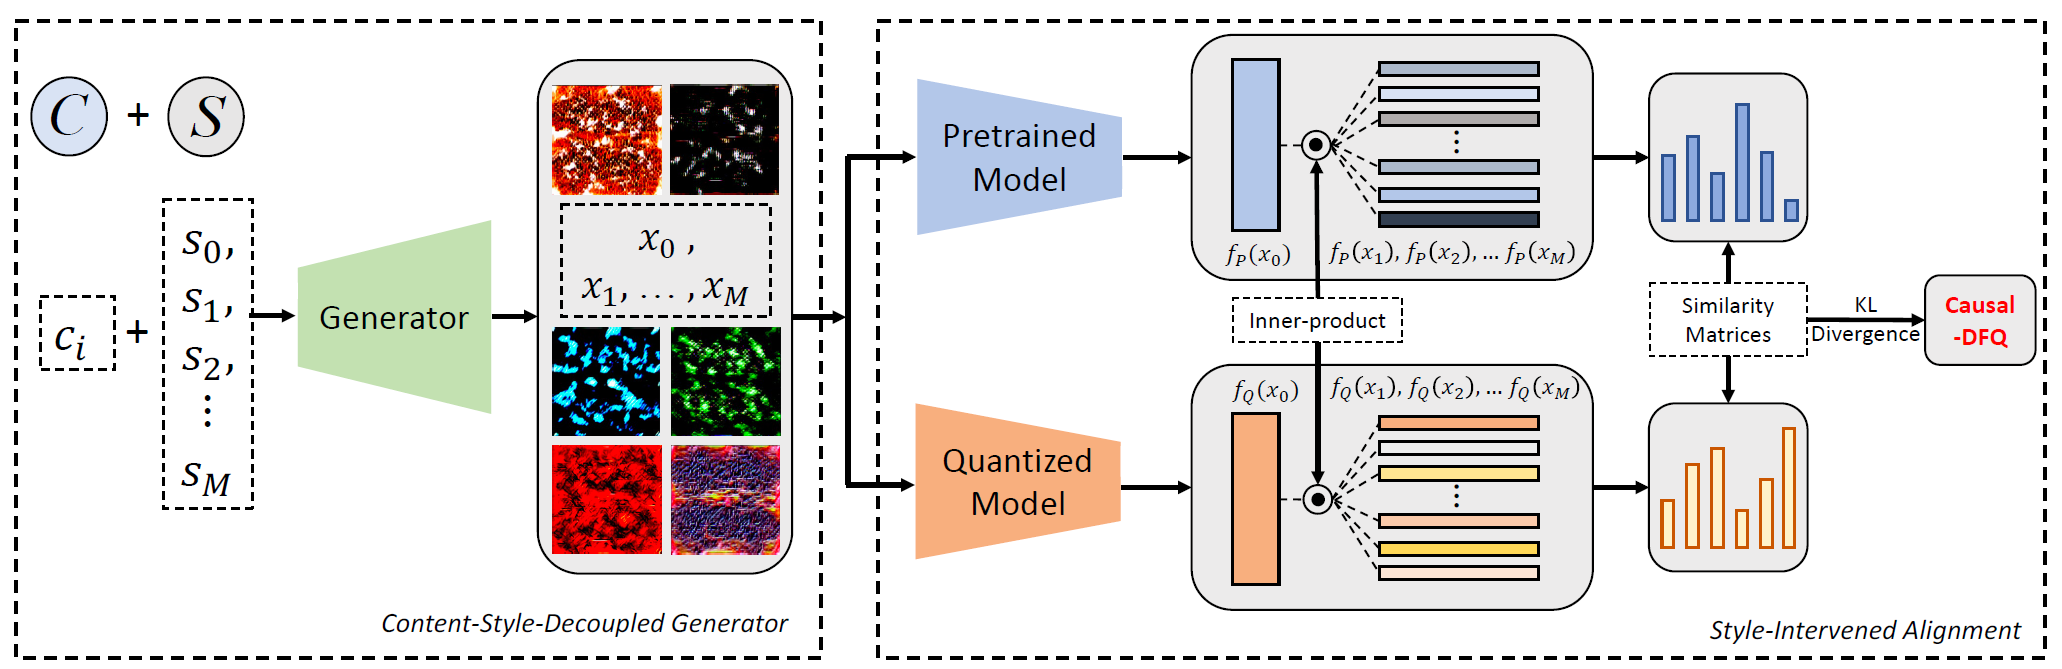
Model quantization, which aims to compress deep neural networks and accelerate inference speed, has greatly facilitated the development of cumbersome models on mobile and edge devices. There is a common assumption in quantization methods from prior works that training data is available. In practice, however, this assumption cannot always be fulfilled due to reasons of privacy and security, rendering these methods inapplicable in real-life situations. Thus, data-free network quantization has recently received significant attention in neural network compression. Causal reasoning provides an intuitive way to model causal relationships to eliminate data-driven correlations, making causality an essential component of analyzing data-free problems. However, causal formulations of data-free quantization are inadequate in the literature. To bridge this gap, we construct a causal graph to model the data generation and discrepancy reduction between the pre-trained and quantized models. Inspired by the causal understanding, we propose the Causality-guided Data-free Network Quantization method, Causal-DFQ, to eliminate the reliance on data via approaching an equilibrium of causality-driven intervened distributions. Specifically, we design a content-style-decoupled generator, synthesizing images conditioned on the relevant and irrelevant factors; then we propose a discrepancy reduction loss to align the intervened distributions of the pre-trained and quantized models. It is worth noting that our work is the first attempt towards introducing causality to data-free quantization problem. Extensive experiments demonstrate the efficacy of Causal-DFQ.
2023